 Oct 13, 2026, 12:34 AM
Thanks, Google. Thoogle.
 Oct 13, 2026, 12:34 AM
Thanks, Google. Thoogle.
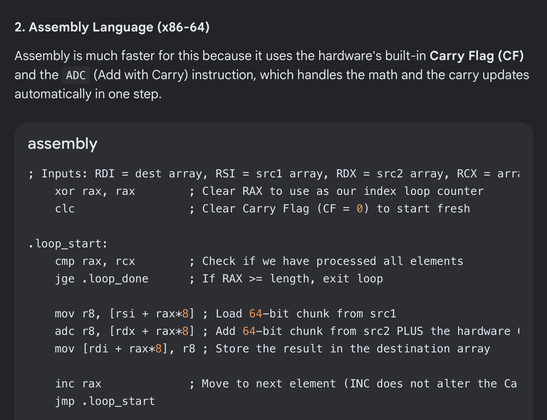
Oct 13, 2026, 12:47 AMOne weird trick to go faster by breaking the loop-carried dependency chain. Validation suites hate it!
@steve the best part about 64-bit carry shenanigans is that if you're not specifically testing for it, you can have bugs for an outrageous amount of time until somebody notices
(more of an issue with x86-64 style carry/borrow, with ARM-style true carry you will probably notice on the first subtraction)
@steve although in this case it'll actually set CF=1 every time which you would presumably notice very quickly
Oct 13, 2026, 1:29 AM@rygorous it's been long enough since I've thought about bignums on x86 that I'm actually not sure what the preferred idiom is these days, but it sure as heck isn't whatever this is.
Oct 13, 2026, 1:32 AM@rygorous it does manage to generate a correct loop for armv8, at least.
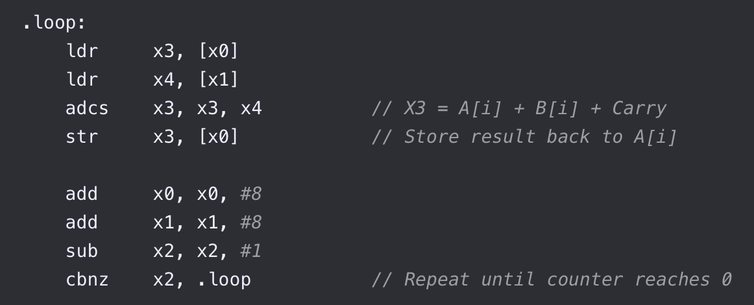
@steve with a truly impressive loop overhead to work fraction no less
Oct 13, 2026, 1:40 AM@rygorous If you only care about Apple Silicon, this will be not-terrible, since the cores are so absurdly wide now. If you just roll the increments into the LDR/STR, me pulling numbers out of my ass (which is generally more accurate than any public simulator) says this will asymptotically get you within about 30% of what you can get by unrolling, with lower fixed cost, so it's actually probably a good choice for most workloads.
If you care about narrower cores, at all, yeah it should be 2x unrolled so you can benefit from LDP/STP.
@steve something something dual carry chains with ADCX/ADOX.
Not relevant for actual adds but does matter for muls.
No idea how you handle loops when you have to.
Presumably unroll and spill/restore carry/overflow into a designated landing pad reg around the test
@steve idly wondering whether you can do something like
mov r8d, 0
adcx r8d, r8d
adox r8d, r8d
shl r8d, 30
to save and then
add r8d, r8d
to restore. That will give you carry back, but I always forget what exactly overflow was. Carry-in into MSB != carry-out, right?
in this case carry-out from MSB is saved_CF and carry-in is saved_OF, so it would set OF to saved_OF^saved_CF.
Almost. Pity. No actual use for it but it felt cute. :)
@steve anyway, with low-ish trip count, probably something like
sub rdx, rsi
sub rdi, rsi
clc
lp:
mov rax, [rsi]
adc rax, [rdx + rsi]
mov [rdi + rsi], rax
lea rsi, [rsi + 8]
dec rcx
jnz lp
or maybe (probably not)
lea rsi, [rsi + rcx*8]
lea rdx, [rdx + rcx*8]
lea rdi, [rdi + rcx*8]
neg rcx
jz skip
clc
lp:
mov rax, [rsi + rcx*8]
adc rax, [rdx + rcx*8]
mov [rdi + rcx*8], rax
inc rcx
jnz lp
Oct 13, 2026, 1:58 AM@rygorous yeah, that feels about right. `neg rcx` was pretty standard when I cared about this, FWIW (but x86 is wider now than it was then).
@steve amazing
@steve thants