Login
You're viewing the corneill.es public feed.
  • Oct 24, 2026, 12:10 PM

    Foly huck. A small story about LLMs.

    For historical reasons, I have a spare cassette for road bikes and it is not compatible with any of my own bikes so I want to sell it. Decided it would be helpful for buyers to include the teeth count of the smallest and largest sprocket in the ad, and was in a lazy Saturday afternoon mood so took a picture, gave that to #chatgpt and asked it to do the counting for me. Answer: 36 teeth.

    That sprocket size doesn't exist in the Shimano universe.

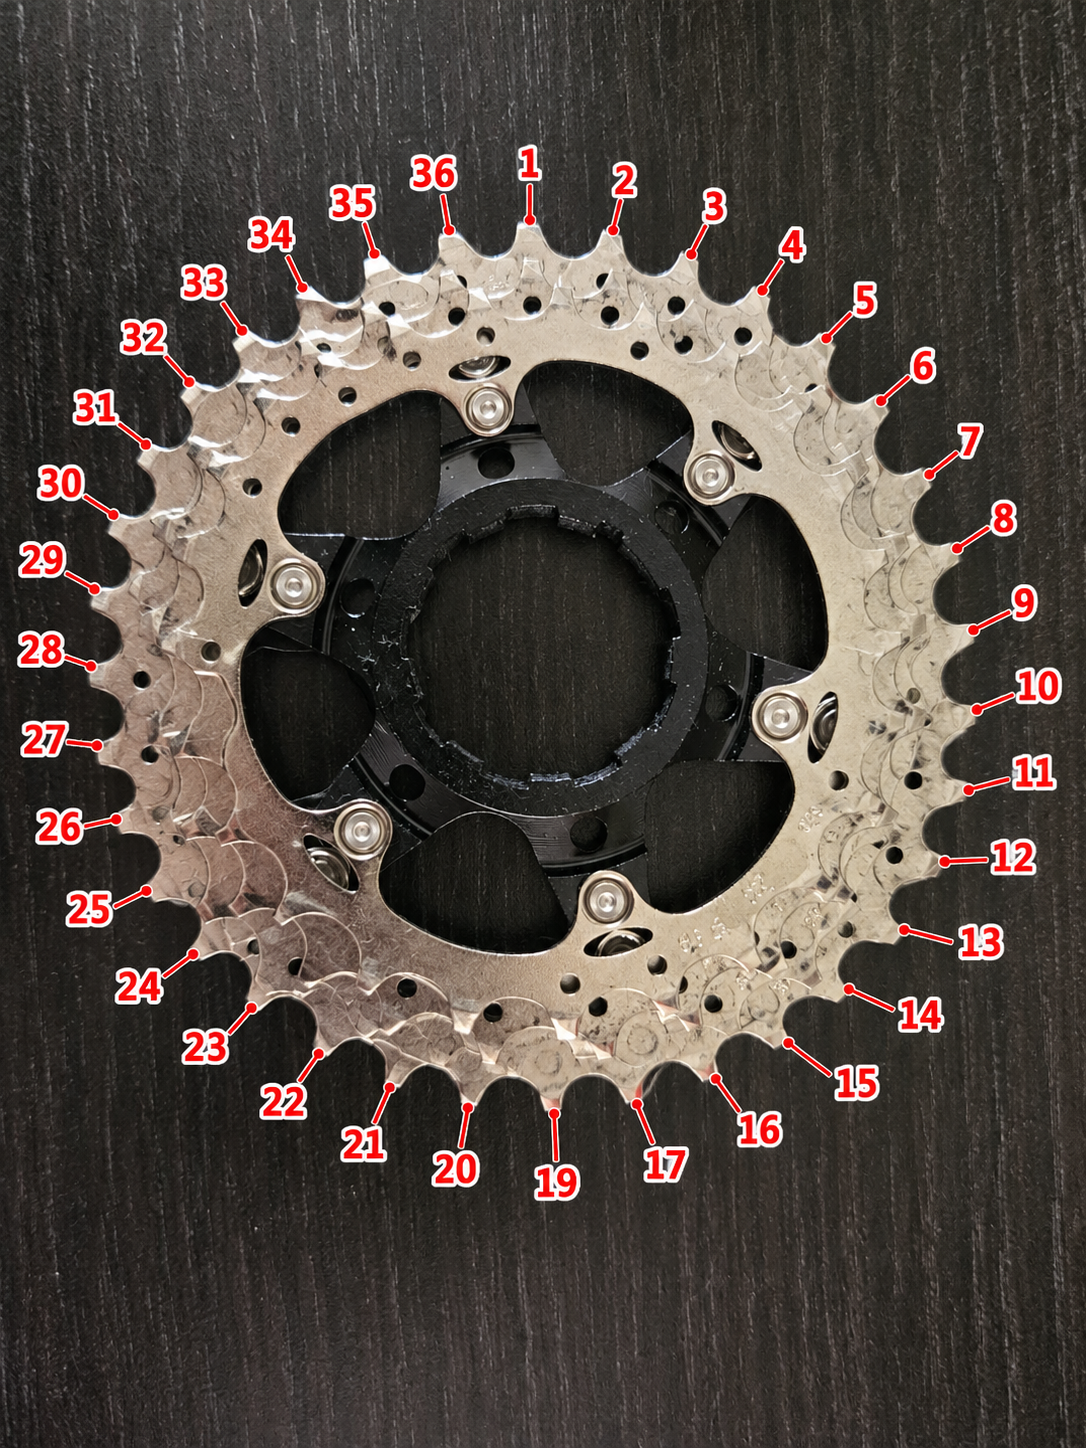
    So I tried to verify its count by asking it to add an increasing number next to every tooth. It complied, and the numbers ran from 1-36. That pictures is included below. You can stop reading now, look at the picture and count along.

    If your ADD is not too bad, you'll notice it skipped 18, so we have 35 teeth. Not 36.

    However that also doesn't exist in the Shimano universe.

    Being as confused as the average republican, I demanded a #recount! It told me 36 again.

    Sigh. Decided to do a manual recount while holding the sprocket in my hand. 28. That is a valid size.

    Then I looked at the photo with counts again. Turns out the clanker took my original photo as inspiration, and fabricated a photo of a sprocket with 35 teeth. I am not sure what triggered it to do that and I do not want to know.

    Your average #LLM is still as bad at counting as they were a year ago. Maybe worse.

    Also, do not invest in that stuff ok?
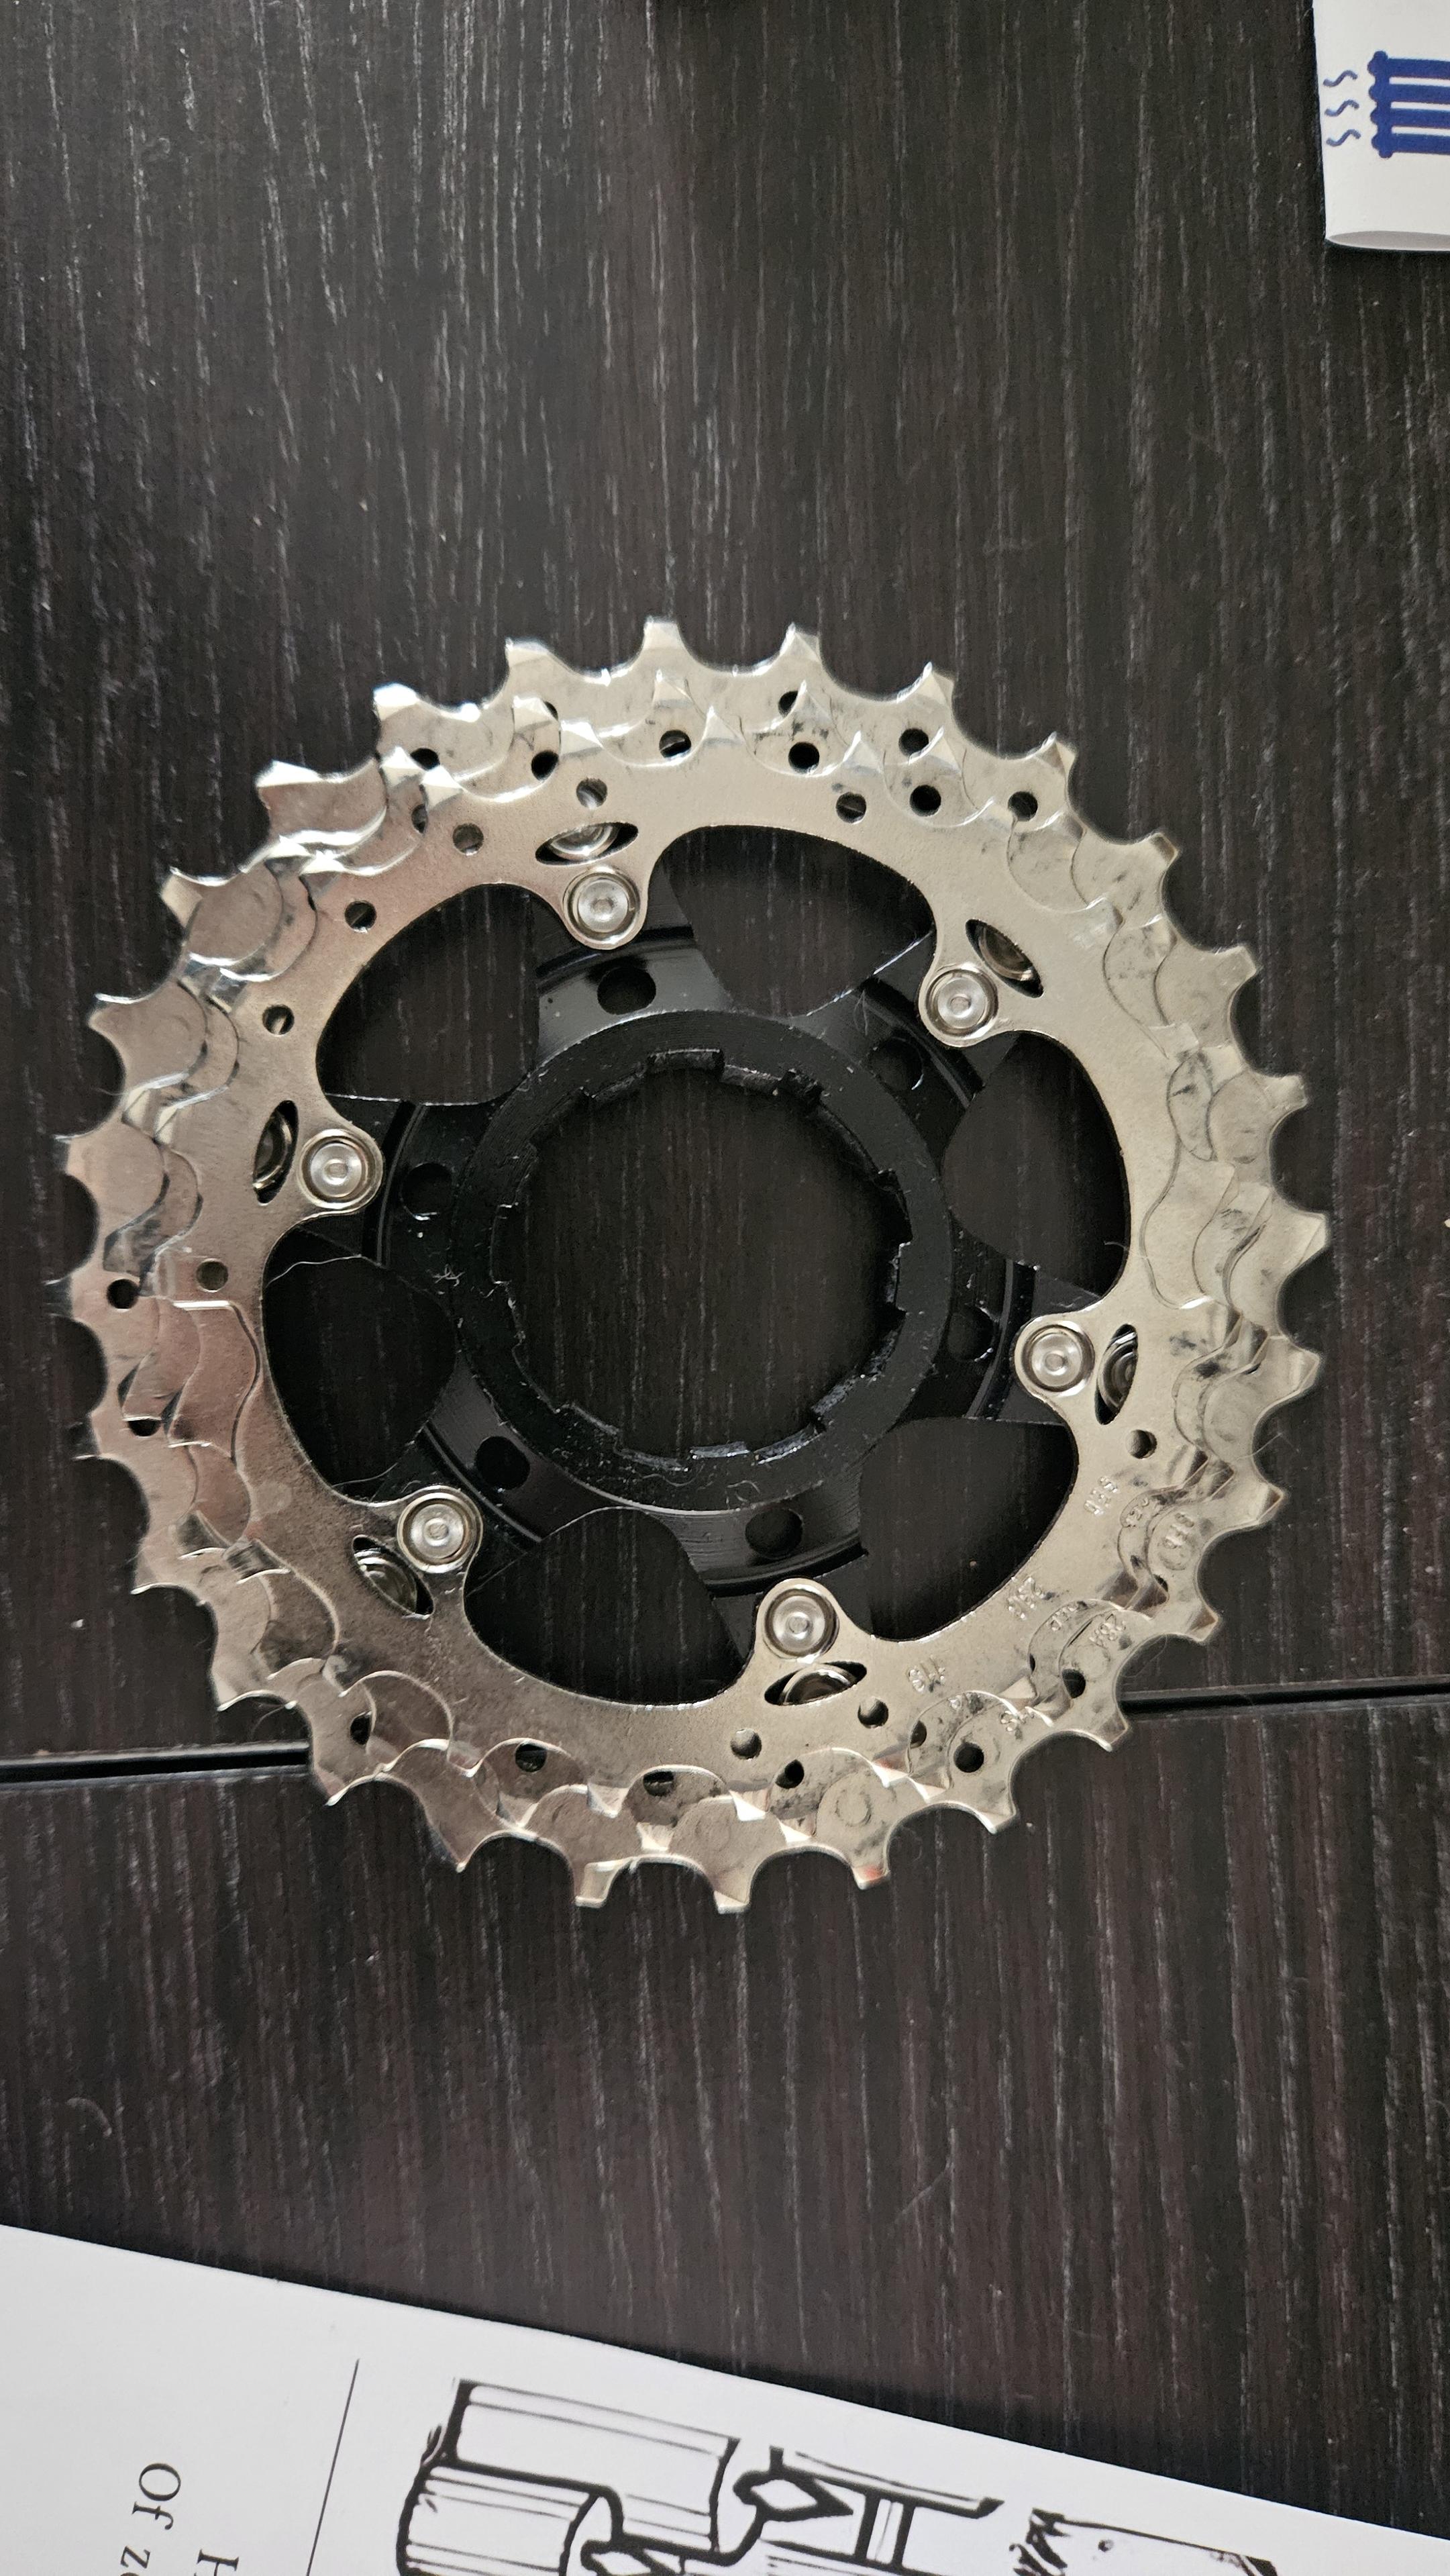
    A photo of the three largest sprockets on a road-bike cassette.
    A photo of - allegedly - the same road bike cassette, after asking ChatGPT to add numbers to verify its reported teeth count.
Notice there is no ’18’. Actually it is a completely different photo that was generated out of thin air, taking the original one as inspiration apparently.
    💬 16🔄 170⭐ 148

Replies

  • Oct 24, 2026, 10:38 PM

    @jap this, by the way, is a good way to see the actual limits of nodern chat-bots: take a personnal hobby you're very good at and query the slop machine to extrude an explanation or answer for something non trivial that you know very well. Be prepared to be extremely disappointed. This is the same "quality" of "answers" the slop machines have been extruding each time you queried about something you're not fluent in, you merely didn't notice how much of a garbage the "answer" was.

    💬 4🔄 19⭐ 30
  • 💬 0🔄 5⭐ 4
  • Oct 25, 2026, 6:32 AM

    @dryak

    I actually did notice that mastodon.sdf.org/@argv_minus_o and of course this makes me wonder what *else* it's blatantly wrong about.

    And as I mentioned in that thread, it gave its blatantly wrong answers with the utmost confidence…while also adding a freaking security vulnerability to the code I asked it to fix.

    These kinds of bots are now being used to develop the operating system and much of the software I use. God help me.

    @jap

    💬 0🔄 1⭐ 2
  • Oct 25, 2026, 6:37 AM

    @dryak @jap LLMs are good at providing precise answers on the surface of the topic you’re interested in at the moment, not at doing deep dives.

    For example, they’re good at debugging students-level R code.

    They’re good at doing research online for you and giving you sources. But that’s because the cyberspace is in a pretty bad shape. There are far-right platforms, paid platforms, techies platforms (static hosting/prose.sh/etc.), and there’s the Gemini protocol.

    💬 0🔄 0⭐ 0
  • Oct 25, 2026, 6:40 AM

    @dryak @jap Or ask them a series of loaded/leading questions on a topic you know well, and observe them generate different, contradictory answers - effectively proving they they have no internal representation of the world against which to fact-check their own outputs. They're just confabulating whatever responses you're statistically most likely to expect based on how you phrased the prompt.

    In similar fashion, if you ask them to explain a nonsensical saying that you just made up, they will. 🤷🏻‍♂️

    💬 0🔄 0⭐ 2
  • Oct 24, 2026, 10:58 PM

    @jap And the answer was in front of the AI the whole time. Stamped on the sprockets; 28A, 25B, 23C.

    known as a 23-25-28T

    💬 1🔄 0⭐ 5
  • Oct 25, 2026, 7:52 AM

    @geoffl @jap
    To sum it up, it seems like this is going to help us remake the world (for the better...?), and it can't count or read—so be suspicious...

    💬 0🔄 0⭐ 0
  • Oct 24, 2026, 11:17 PM

    @jap That sounds like a dumb GPT. Which model did you use? I ran your photo through Claude Opus with a very simple prompt and it got the number correct right away, and pointed out that the smallest cog of this cassette isn't in the picture and thus can't be assessed.

    💬 2🔄 0⭐ 0
  • 💬 0🔄 0⭐ 3
  • 💬 0🔄 0⭐ 1
  • Oct 25, 2026, 7:59 AM

    @nils I used whatever the Android mobile app for ChatGPT signed in with a free account uses - it doesn't let you select one explicitly it seems. Desktop app signed into the same account defaults to “6 Luna" so my guess is that that is what is used on mobile. Not the frontierest of models. Yet it is the model used by the non-tech folks who hear about AI, install ChatGPT because that is the name they've heard most often, and then start asking it questions - without questioning its answers.

    Do note however that the story was not about the model initially miscounting.

    It was about what happened afterwards: it bent the truth to fit its previous mistake. That is the freaky thing!

    💬 1🔄 1⭐ 2
  • Oct 25, 2026, 8:06 AM

    @jap Yeah, the fact that it would create it's own "evidence" to prove a faulty assessment is kinda ridiculous.

    💬 0🔄 0⭐ 1
  • Oct 24, 2026, 11:20 PM

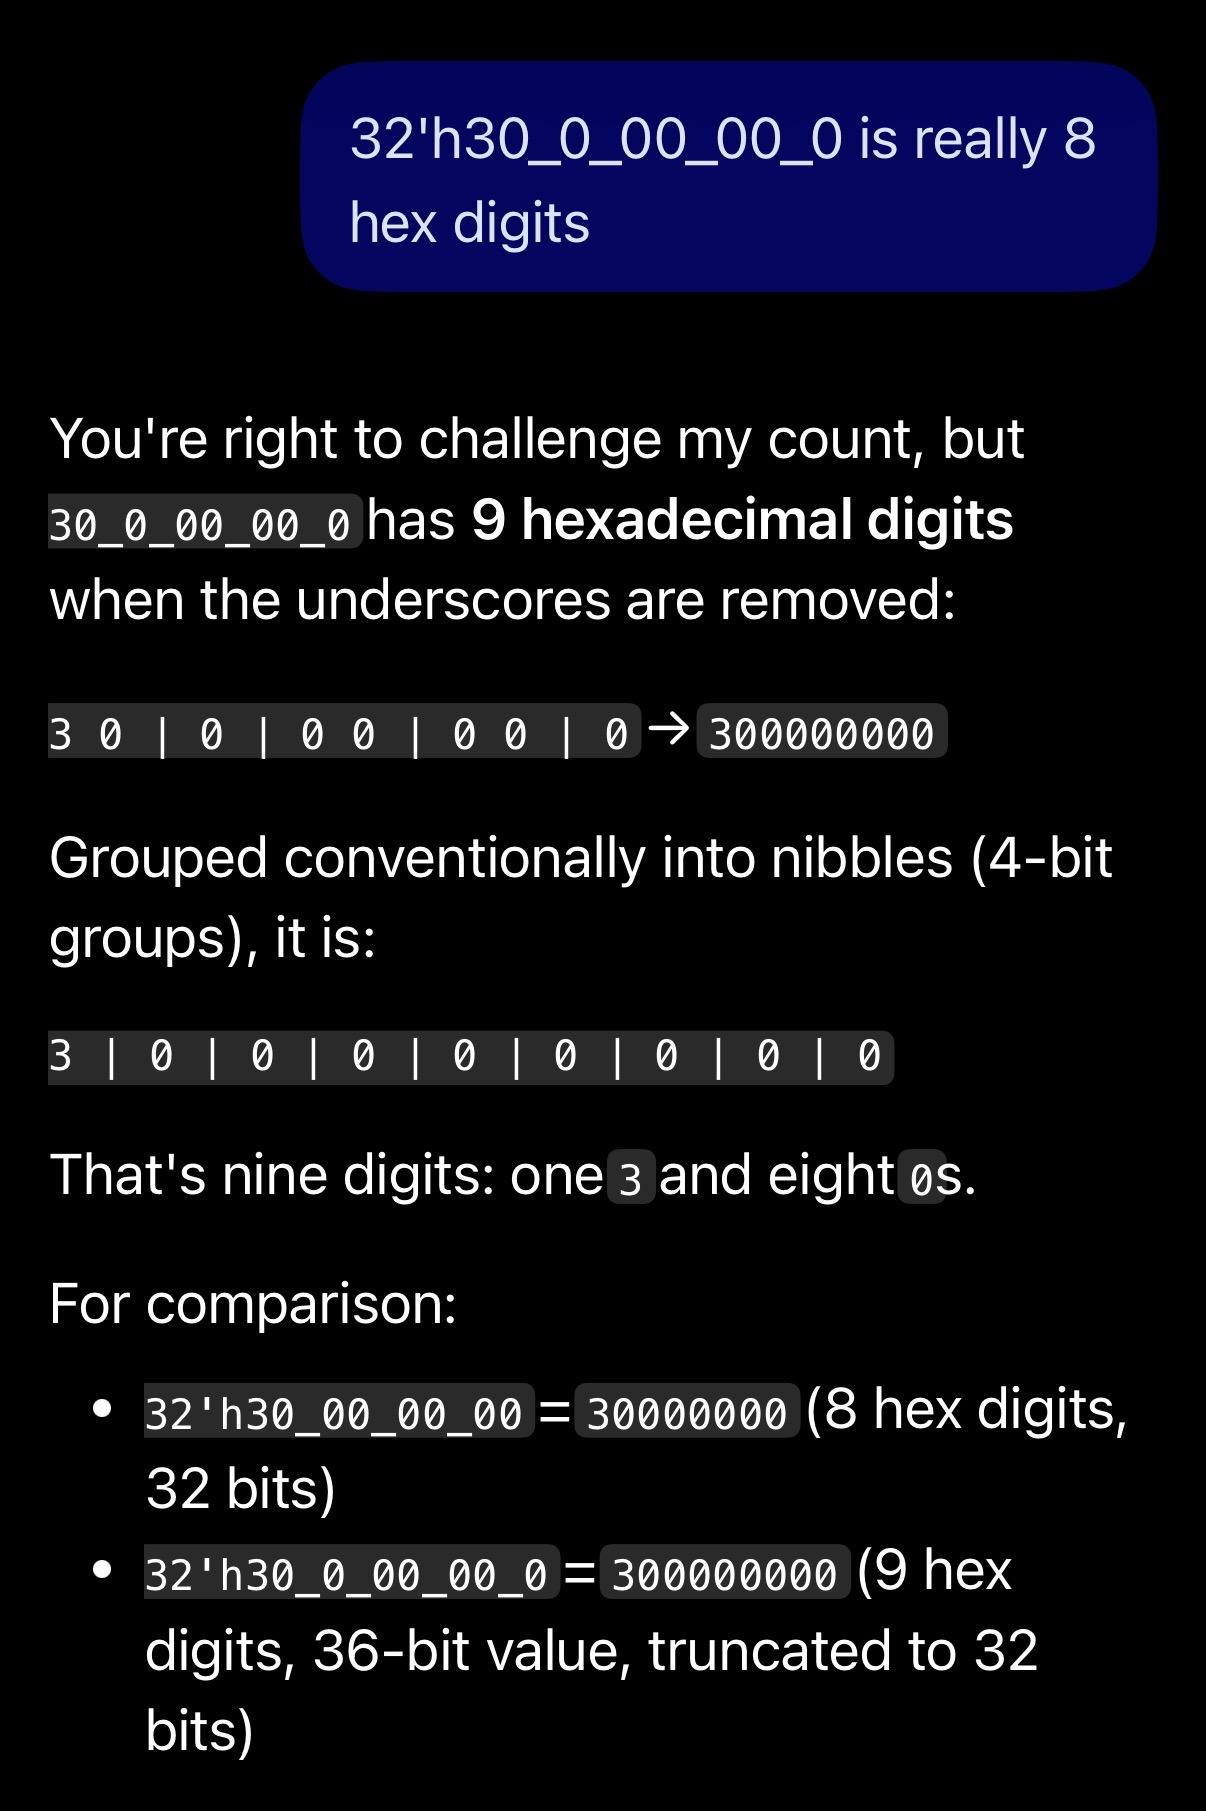
    @jap I think it is indeed (fundamentally?) incapable of counting as I found out again this evening...

    Screenshot of copilot with prompt: "32'h30_0_00_00_0 is really 8 hex digits" and wrong reply: "You're right to challenge my count, but 30_0_00_00_0 has 9 hexadecimal digits when the underscores are removed:
3 0 | 0 | 0 0 | 0 0 | 0 → 300000000
Grouped conventionally into nibbles (4-bit groups), it is:
3 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0
That's nine digits: one 3 and eight 0s.
For comparison:
32'h30_00_00_00 = 30000000 (8 hex digits, 32 bits)
32'h30_0_00_00_0 = 300000000 (9 hex digits, 36-bit value, truncated to 32 bits)
    💬 1🔄 0⭐ 0
  • Oct 25, 2026, 7:56 AM

    @vaneeten Yes: LLMs fundamentally, as an inevitable consequence of how they're designed, can't count and can't spell(*) and can't reason. All they can do is predict the likelihood of the next words in their answer to follow the previous words in the 'conversation', based on what they've ingested in their training data. Sometimes this results in an 'answer' that's correct, and people go "Wow, look how clever it is!" And sometimes it results in an 'answer' that's wrong, and people go "Oh you just need to prompt it better."

    (*) cf the berry spelling problem

    @jap

    💬 0🔄 0⭐ 0
  • 💬 1🔄 0⭐ 1
  • Oct 25, 2026, 8:12 AM

    @marjolica Fair point. My escape is that I knew that this is part of a CS-R7000 cassette, and that series goes up to 32. So, in my universe for validating the response, a cassette with a 36t sprocket does not exist.

    💬 0🔄 0⭐ 0
  • Oct 25, 2026, 4:40 AM

    @jap this is a very interesting finding in a sense that it very clearly suggests what is the difference between human thinking and LLM operation. I might have been formulating this as difference between human and LLM intelligence, but that would spark unnecessary debate ;) Anyhow, if there will be anything like machine intelligence and thinking robots in the future, it will not necessarily be human like - as this demonstration warns.

    💬 1🔄 0⭐ 0
  • Oct 25, 2026, 6:09 AM

    @jap At first it miscounted which is still a known "feature" of LLMs. Then, when you instructed it to make a drawing with the numbering labels, it took not only your image as inspiration, but its own previous counting result (32) as well. So it drew a sprocket with 32 cogs. Better to say, it tried to do that, but failed as the sprocket had 31 cogs. Then it labelled it and had to make a nice trick (leave out number 18) to get the desired result.

    💬 0🔄 0⭐ 0
  • Oct 25, 2026, 6:10 AM

    @jap
    I think the main take-away is that "facts" represent a problem for LLMs. It is anyhow a difficult concept that fails miserably in our human society as well nowadays, but for LLMs it is a weakness from the very beginning - and that is originating from the design. There are solutions for that, but those are not implemented in the chatbot versions.

    💬 0🔄 0⭐ 0
  • 💬 1🔄 0⭐ 2
  • 💬 0🔄 0⭐ 0
  • Oct 25, 2026, 7:44 AM

    @jap When writing the prompt is harder than doing the job yourself: no, do not reinvent a brand new product. Follow the simple instructions.

    💬 0🔄 0⭐ 0
  • Oct 25, 2026, 8:11 AM

    @jap the actual problem here is asking the slop machine to count it in the first place. Why cant you count it yourself first? I think my 7yo can do that. Without burning the planet even.

    💬 0🔄 0⭐ 1
  • 💬 0🔄 0⭐ 2
  • Oct 25, 2026, 8:24 AM

    @jap Damn. Really wild. Also, now substitute counting sprockets with assigning military targets. Have a nice peaceful Sunday everyone.

    💬 0🔄 0⭐ 0
  • Oct 25, 2026, 8:28 AM

    @jap I think it is a real problem is ChatGPT and when you not have finetuned it not the system LLM. This for example is the answer from Claude - same question as you no help - just the picture

    Image attached toot
    💬 0🔄 0⭐ 0
  • Oct 25, 2026, 8:51 AM

    @jap Also, stunning example that if you're doing anything you care about in the least, the work of verifying the ouput will often far exceed the work of doing the thing yourself to begin with...

    Basically, if you ever catch yourself thinking "Maybe AI can help with this", that's your first mistake.

    💬 0🔄 0⭐ 0
  • Oct 25, 2026, 9:51 AM

    @jap step 1 is the problem.

    Why? Like, it takes maybe 30 seconds to count teeth. You decided to burn the planet to the ground to count cassette teeth.

    I'm sure, if you spent more than 30 seconds on it, you'd find an etched model number that wouldn't just give you teeth, but what actual model it is.

    But I suppose it's easier to burn the planet to the ground for a funny post on the fediverse, eh?

    People like you sicken me. You act like you're anti-AI, but you're their perfect customer

    💬 0🔄 0⭐ 2
  • Oct 25, 2026, 11:27 AM

    @sortius @jap Don't be sickened: everybody has to learn just how bad LLMs are at basic tasks for themselves by making one perform an "obvious" job and seeing how wrong they get it. Once you've seen it *for yourself* it can never be unseen. (Admittedly some people may need to do it two or three times before they realize it's unpredictably bad at *everything*.)

    💬 0🔄 0⭐ 0
  • 💬 0🔄 0⭐ 0
  • Oct 25, 2026, 11:29 AM

    @jap

    If I had used chatgpt to count the teeth on the sprockets for the manufacturing lines and stock up the parts room with spare belts and sprockets, we would have about one week until we needed one of those wrong parts. About 50 people on the clock for about three shifts would be idle until the part came in. And a lost day of production. Production lines burn money sitting idle, electricity, permits, unfulfilled contracts, support contracts, etc. About half million dollar loss not having the correct part in stock.

    💬 0🔄 0⭐ 0